Normalize company names before you compare them
Raw company names are poor matching keys because punctuation, capitalization, suffixes, spacing, and abbreviations create false differences. A normalization step can standardize case, trim extra spaces, remove punctuation where appropriate, and separate common legal suffixes such as LLC, Inc., Ltd., or Corp. from the core name used for matching.
Normalization should create a comparison value, not overwrite the original company name. Keep the original display value so the final record can retain the most useful business-facing name after matching is complete.
- Preserve the original name
- Create a separate normalized comparison field
- Standardize punctuation and spacing
- Handle legal suffixes consistently
- Document abbreviation rules instead of improvising them row by row
Use more than the company name
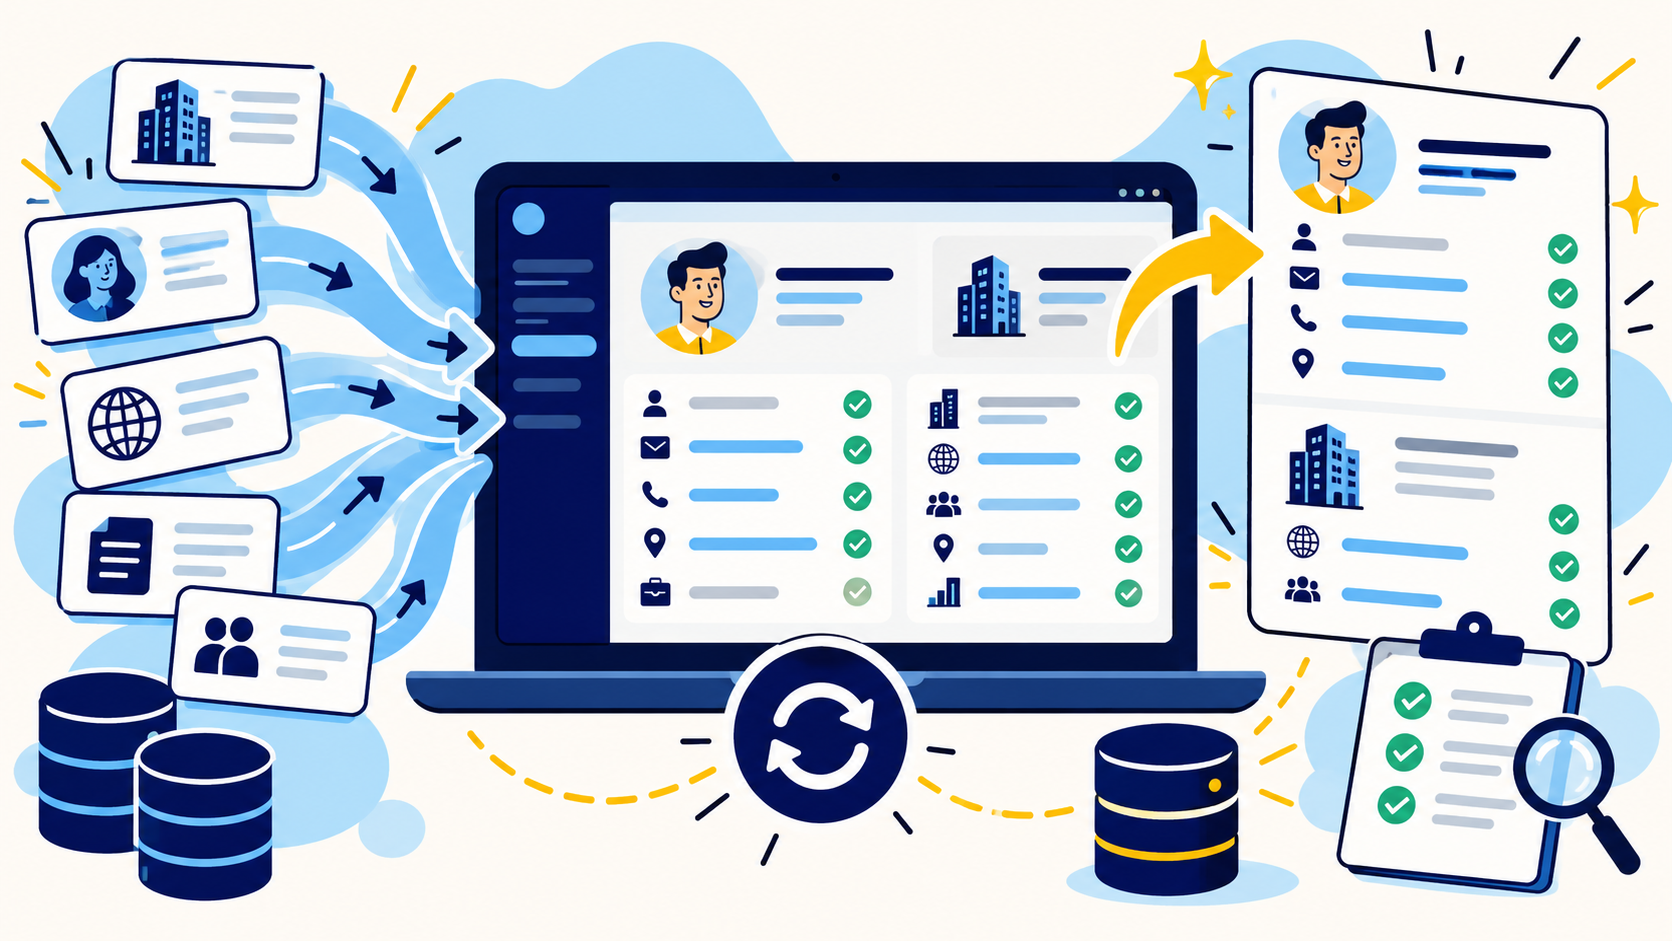
Two records with nearly identical names may still be different companies, while two records with different names may belong to the same company. Stronger matching uses additional fields such as website domain, headquarters location, address, phone, parent company, or a stable company identifier.
Website domain is often one of the best business-level keys because it is more stable than a display name, but it is not perfect. Subsidiaries, franchises, business units, and companies with multiple brands can legitimately use different domains.
Separate exact matches from fuzzy matches
Exact matches can usually be handled automatically when the matching key is trustworthy. Examples include identical normalized domains or identical normalized company names plus the same location. Fuzzy matches need a confidence threshold and often a second field before they can be safely merged.
String similarity is useful for catching spelling differences and abbreviations, but it should be treated as evidence rather than proof. A similarity score cannot understand business structure on its own.
- High confidence: same domain and compatible company name
- Medium confidence: similar name plus same location or address
- Low confidence: similar name only
- Manual review: parent-child, franchise, acquisition, or brand ambiguity
Define the business entity you are deduplicating
Before merging records, decide whether the file is supposed to represent legal entities, operating brands, parent companies, physical locations, or sales accounts. The same dataset can have different correct answers depending on that definition.
For example, a restaurant chain may be one account in a corporate sales model and hundreds of distinct locations in a local-market project. Deduplication should preserve the grain of the dataset rather than forcing every related record into one master row.
Use survivorship rules to keep the best values
Finding duplicates is only half the work. The merge step needs field-level survivorship rules that decide which value wins. The newest value may be best for employee count, while a verified website or source-backed legal name may deserve priority over a newer but less reliable value.
DataDabble typically treats provenance, verification status, source quality, recency, and completeness as separate signals. That makes the merge explainable and reduces the risk of replacing a strong value with a weaker one simply because it arrived later.
Keep an audit trail for merged records
For important business data, record which rows were grouped, which record survived, and why. A simple merge log can preserve original IDs, matched IDs, match method, confidence, and the chosen surviving record.
This becomes especially useful when the file feeds a CRM, routing system, reporting model, or recurring enrichment process. If a merge is questioned later, the team can reconstruct what happened without starting over.
Review the edge cases manually
The hardest duplicates are usually not spelling mistakes. They are acquisitions, subsidiaries, franchises, rebrands, holding companies, shared addresses, and companies that operate several websites. Those cases benefit from public web research and human judgment.
A good deduplication process automates obvious matches and reserves manual review for the records where the business relationship actually matters. That is faster and safer than trying to automate every case with one threshold.
Common questions
What is the best field for deduplicating company records?
There is no universal best field. Website domain is often strong, but reliable matching usually combines company name with domain, location, address, identifiers, or other business context.
Should legal suffixes like LLC or Inc. be removed?
They can be removed from a normalized comparison field, but the original company name should be preserved for display and reference.
Can fuzzy matching safely deduplicate a company list by itself?
Not reliably. Fuzzy matching is useful for candidate generation, but ambiguous matches should be checked against additional company fields or reviewed manually.
What should happen to duplicate rows after a match?
Use field-level survivorship rules to merge the strongest values, preserve source context where needed, and log the relationship between original and surviving records.
Final thoughts
Company-name deduplication looks simple until the same business appears under abbreviations, legal names, brand names, old names, parent companies, and location-specific variants. The goal is not to delete anything that looks similar. It is to decide which records represent the same business entity, preserve the best values, and keep meaningful distinctions intact.
Need help improving your business data?
DataDabble can research, clean, enrich, and maintain the records your team depends on.