
Validation starts with a rule, not a tool
A validation check only makes sense when the expected state is defined. Before reviewing a dataset, decide which fields are required, which formats are accepted, what ranges are plausible, which values must be unique, and what relationships between fields must hold true.
The same value can be valid in one workflow and unusable in another. A blank revenue field may be acceptable for a contact directory but disqualifying in a segmentation project that depends on revenue bands.
Use structural checks to catch obvious defects quickly
Structural validation catches records that fail a predictable rule. These checks are easy to automate and should usually happen before manual review.
Examples include required-field checks, allowed-value lists, data-type checks, length rules, date formats, email syntax, URL structure, numeric ranges, and duplicate identifiers. These checks do not prove that a value is true, but they remove many records that are clearly unusable.
- Required fields are populated
- Values use the expected type and format
- Numbers and dates fall within plausible ranges
- Controlled fields use approved values
- Identifiers that should be unique are not duplicated
Validate relationships between fields, not just individual cells
Many important errors only appear when fields are evaluated together. A contact can have a perfectly formatted email that belongs to a different company. A city and state can each be valid but not correspond to one another. A product variation can contain valid attributes that conflict with the parent record.
Cross-field rules catch these contradictions. For B2B research, company name, website, domain, contact role, and source context should support the same entity.
Source validation is different from format validation
A value can pass every format check and still be wrong. That is where source validation matters. Compare high-impact values against reliable first-party records, official company sources, trusted data providers, or another authoritative reference appropriate to the project.
DataDabble treats source evidence and formatting as separate confidence layers. A clean-looking record should not be labeled verified solely because it fits the schema.
Create explicit outcomes for uncertain records
Validation should not force every record into pass or fail when the evidence is incomplete. Useful statuses can include verified, valid format only, needs review, source conflict, stale, not found, or rejected.
Keeping uncertainty visible is better than filling a field with a value that looks complete but cannot be defended. It also creates a queue for targeted manual research instead of making reviewers recheck the entire dataset.
Run validation before and after transformation
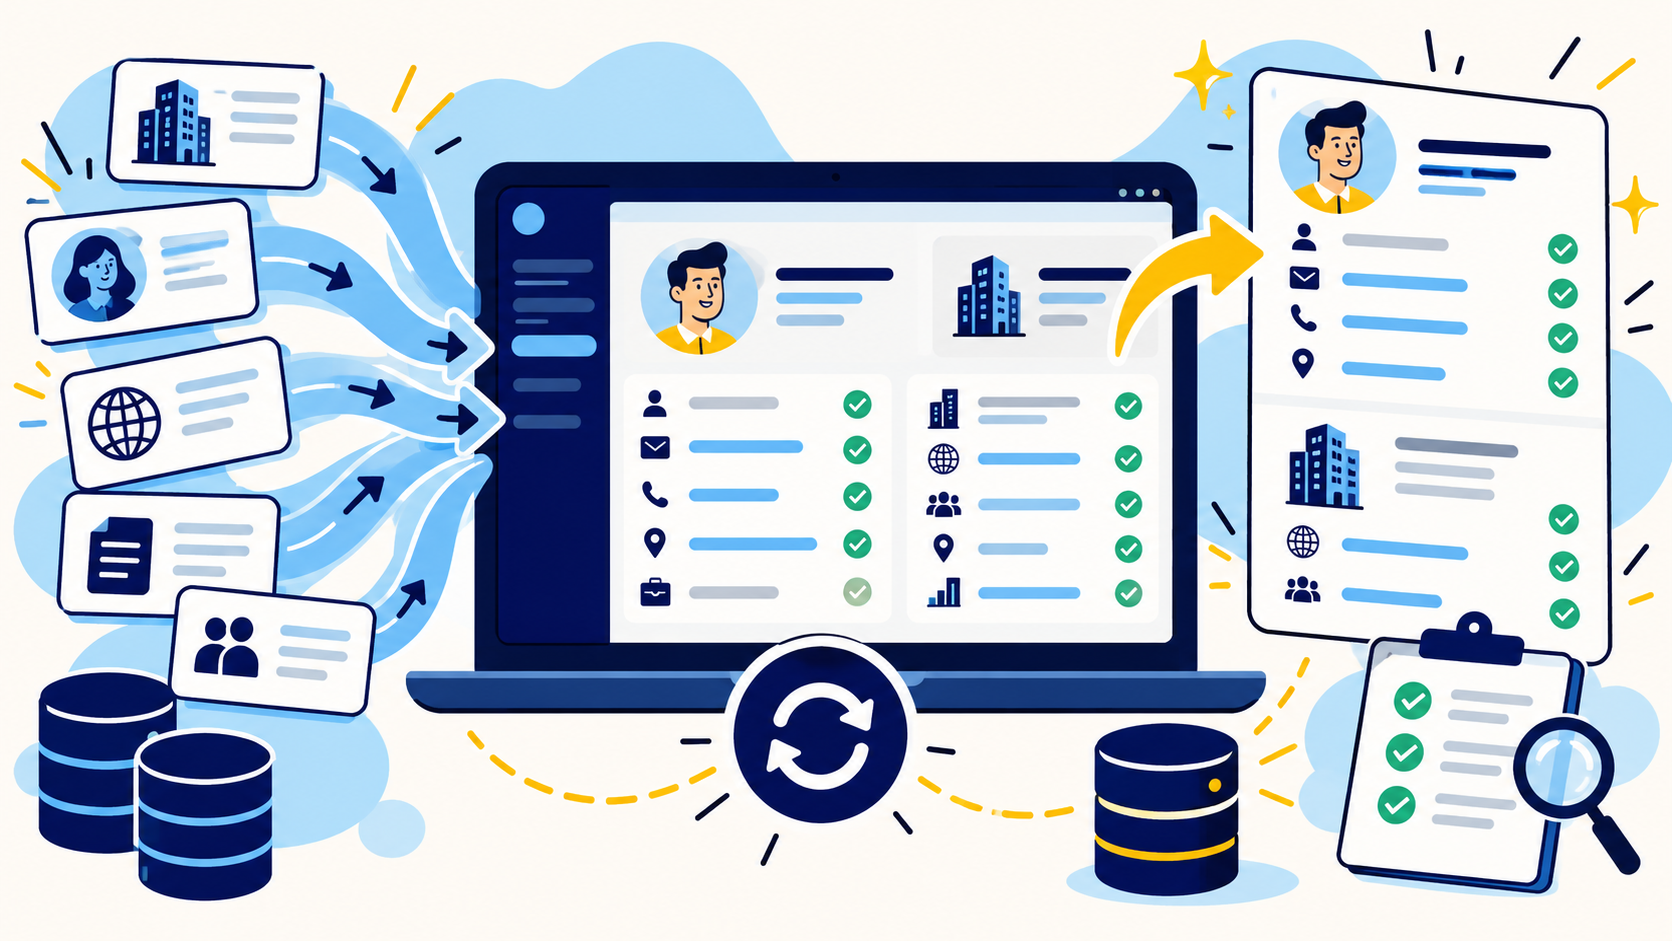
Validation is useful at multiple points. Check raw inputs before transformation so bad records do not contaminate the workflow. Then check the output again after standardization, merging, enrichment, or migration mapping to confirm that the process did not create new defects.
For recurring work, store the rules in code, spreadsheet formulas, database constraints, or workflow checks so the same standard is applied consistently.
Measure validation by business impact, not just pass rate
A 98 percent validation pass rate can still be unacceptable if the failed 2 percent includes the records that determine revenue reporting or the fields used to route every lead. Track failures by rule and by field importance.
The best validation programs make defects actionable: which rule failed, how many records are affected, whether the issue is systematic, and what should happen next.
Common questions
What is data validation?
Data validation checks whether data meets defined requirements for format, range, completeness, consistency, relationships, source confidence, and business use.
What is the difference between data cleaning and data validation?
Data cleaning changes or removes defective data. Validation checks whether the data meets the required rules. Validation often identifies what needs to be cleaned and then confirms the cleaned output.
Can data validation be automated?
Many structural and business-rule checks can be automated. Ambiguous entity matching, source conflicts, and context-heavy research often still require human review.
When should data be validated?
Validate important inputs before transformation and validate outputs again after cleaning, enrichment, migration, or integration work.
Final thoughts
Data validation is the process of checking whether data meets the rules required for its intended use. IBM defines it as verifying that data is clean, accurate, and ready for use. In practice, validation can be simple, such as confirming that a required field is present, or more contextual, such as checking that a company domain belongs to the same organization named in the record.
Need help improving your business data?
DataDabble can research, clean, enrich, and maintain the records your team depends on.